Yong Xien Chng

I'm a PhD student in the Department of Automation at Tsinghua University, advised by Gao Huang.

I'm interested in building models that connect language with the visual world. My work spans visual understanding, multimodal reasoning, and image generation: grounding descriptions in images, gathering evidence to solve problems, and creating images that faithfully follow complex instructions.

Research

Selected work is highlighted.

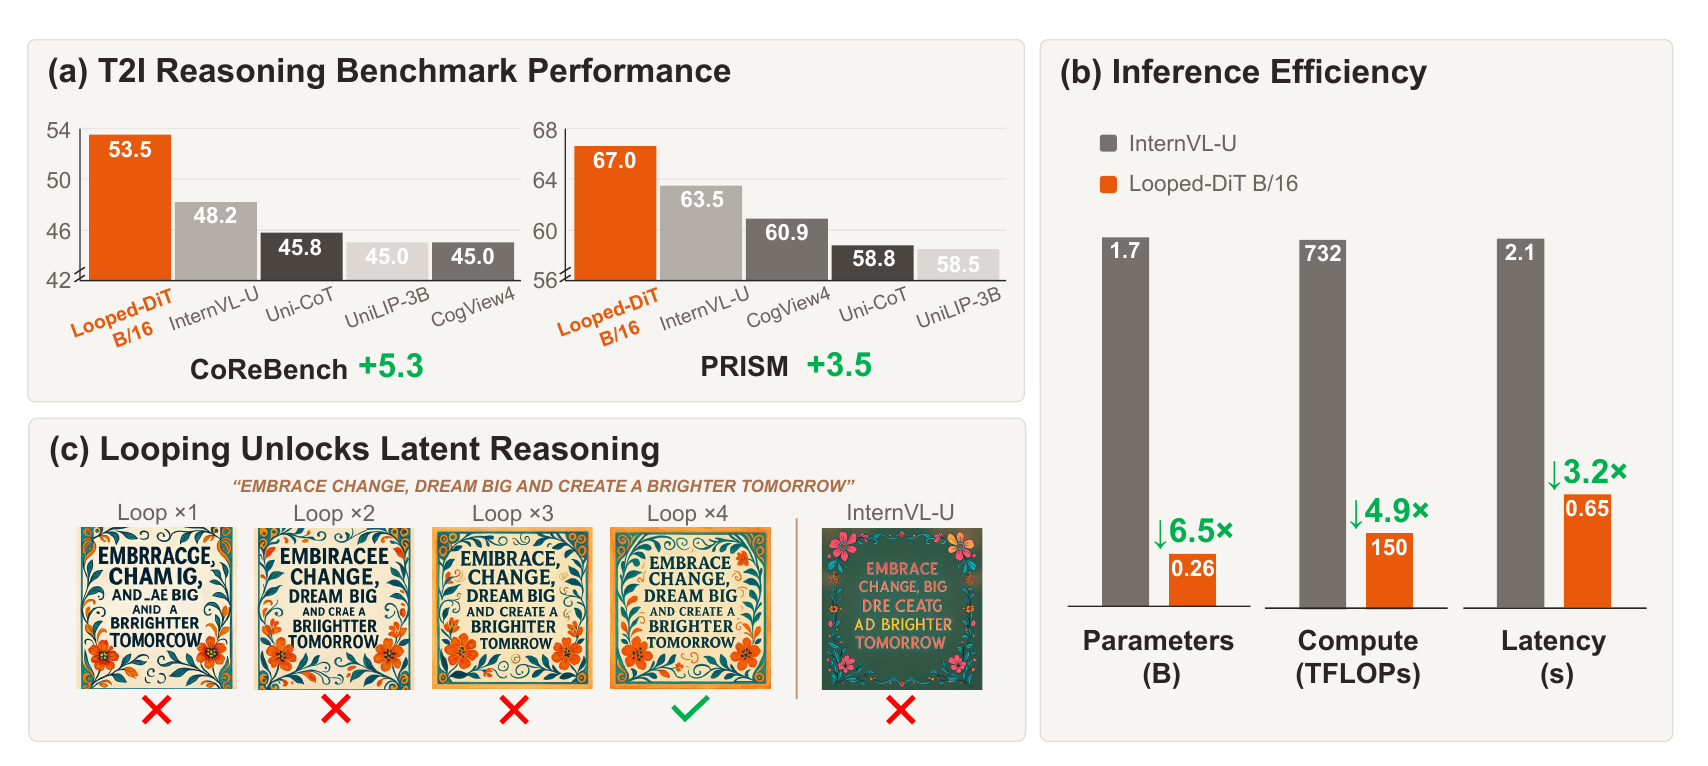
The same prompt rendered at loop depth 1 to 4; the text becomes correct by loop 4.

Looped Diffusion Transformer

Yong Xien Chng, et al.

arXiv preprint, 2026 (under review)

arXiv soonCode soon

Rerun the middle blocks of a diffusion transformer inside every denoising step. A 260M model beats models 6.5× larger at 1/5 the compute, and later loops correct mistakes made by earlier ones.
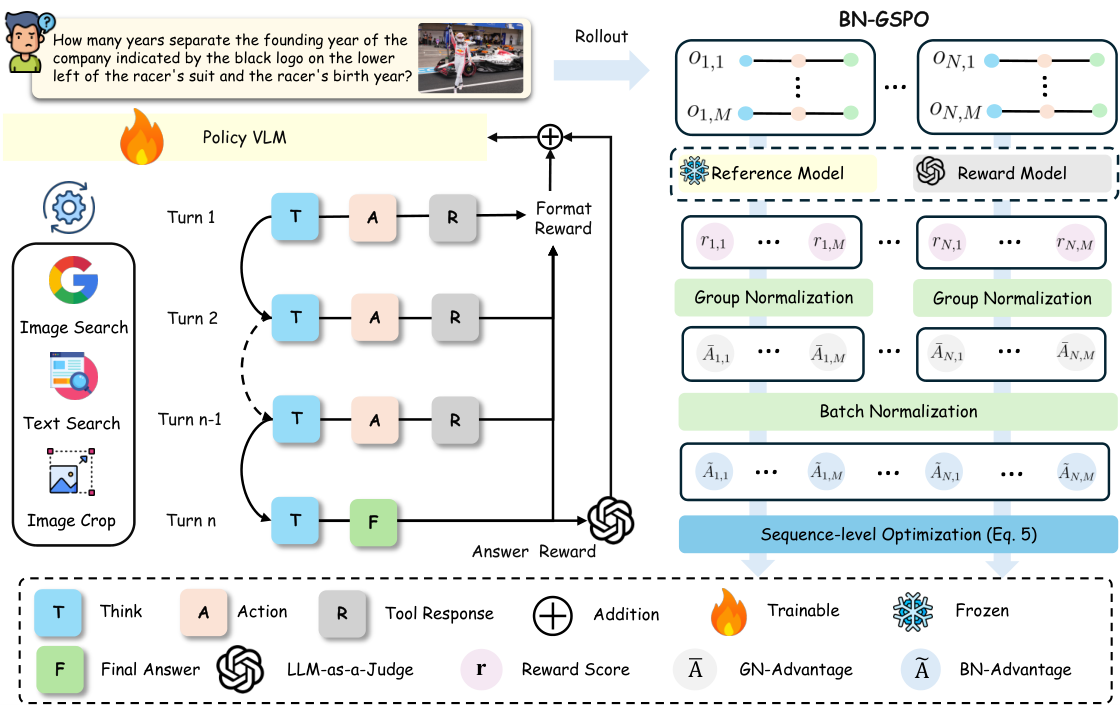
SenseNova-MARS: a policy VLM interleaving image search, text search and image crop tools with reasoning.

SenseNova-MARS: Empowering Multimodal Agentic Reasoning and Search via Reinforcement Learning

Yong Xien Chng*, Tao Hu*, Wenwen Tong*, Xueheng Li, Jiandong Chen, Haojia Yu, Jiefan Lu, Hewei Guo, Hanming Deng, Chengjun Xie, Gao Huang, Dahua Lin, Lewei Lu (* equal contribution)

CVPR, 2026 (Highlight)

CVPR paperarXivCodeModels

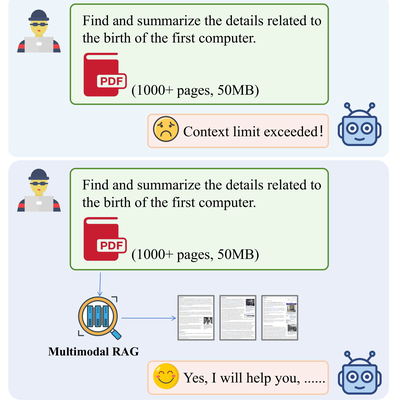
A VLM that searches the web, crops the image and reasons, all in one interleaved loop learned with RL. The 32B model beats Gemini-3-Pro and GPT-5.2 on multimodal search, and we release HR-MMSearch, a high-resolution search benchmark.

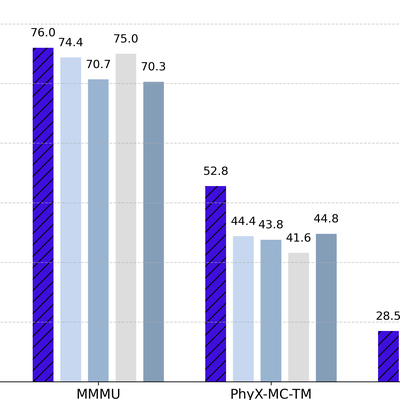
Skywork R1V benchmark bars on MMMU and PhyX against GPT-4.5, GPT-4o and Claude 3.7 Sonnet.

Skywork R1V: Pioneering Multimodal Reasoning with Chain-of-Thought

Yi Peng, Peiyu Wang, Xiaokun Wang, Yichen Wei, Jiangbo Pei, Weijie Qiu, Ai Jian, Yunzhuo Hao, Jiachun Pan, Tianyidan Xie, Li Ge, Rongxian Zhuang, Xuchen Song, Yang Liu, Yahui Zhou

Technical report, 2025

arXivCodeModel

Bringing R1-style chain-of-thought to vision without retraining the LLM or the vision encoder: a light projector, iterative SFT with GRPO, and distilled reasoning chains that know when to stop.

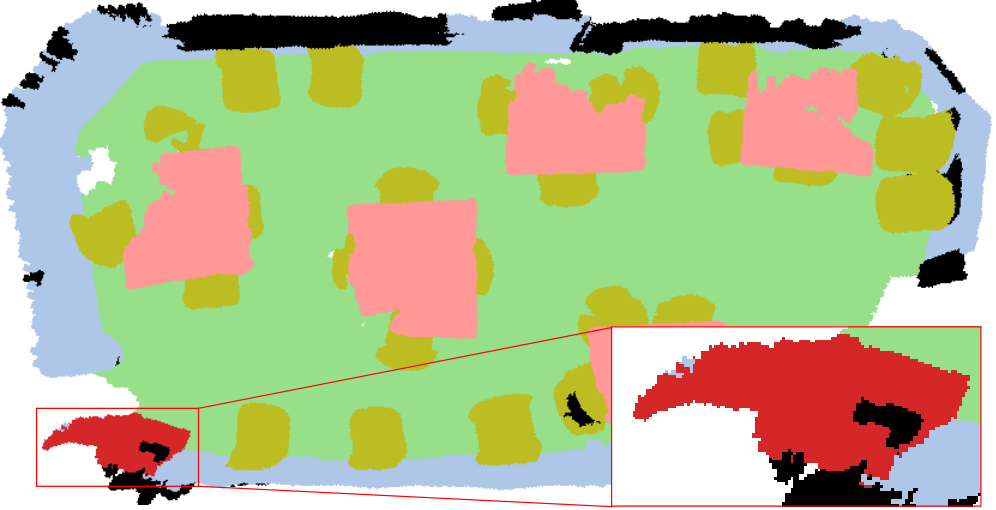
1stChallenge winnerCVPR 2024 · 3D Grounding

DenSeg: Alleviating Vision-Language Feature Sparsity in Multi-View 3D Visual Grounding

Henry Zheng, Hao Shi, Yong Xien Chng, Rui Huang, Zanlin Ni, Tianyi Tan, Qihang Peng, Yepeng Weng, Zhongchao Shi, Gao Huang

CVPR 2024 Autonomous Grand Challenge Workshop

1st place, Multi-view 3D Visual Grounding track. The challenge entry that grew into DenseGrounding.

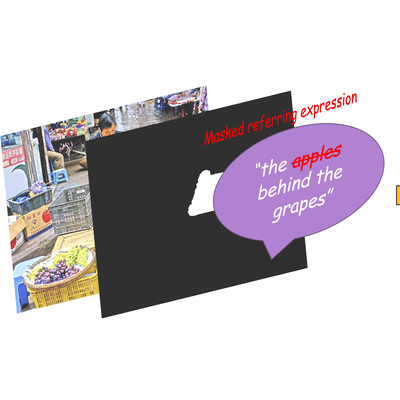
Mask Grounding: a referring expression with one word masked, matched to the object it names.

Mask Grounding for Referring Image Segmentation

Yong Xien Chng, Henry Zheng, Yizeng Han, Xuchong Qiu, Gao Huang

CVPR, 2024

arXivCode

Teach the model which word refers to which object, and referring segmentation gets better. A simple auxiliary task that lifts prior methods and sets the state of the art on RefCOCO, RefCOCO+ and G-Ref.